About of The Engineering Behind Llm Inference Speculative Decoding And Long Context
Looking for the latest information on The Engineering Behind Llm Inference Speculative Decoding And Long Context? We've gathered comprehensive data, records, and insights about The Engineering Behind Llm Inference Speculative Decoding And Long Context.
Key Details
Explore the key sources for The Engineering Behind Llm Inference Speculative Decoding And Long Context.
History
Stay updated on The Engineering Behind Llm Inference Speculative Decoding And Long Context's newest achievements.
What Is LLM Inference How AI Models Generate Responses
The Engineering Behind LLM Inference: The Whole Stack
The Engineering Behind LLM Inference: The Memory Wall
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: October 27, 2026
Future Outlook
For 2026, The Engineering Behind Llm Inference Speculative Decoding And Long Context remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
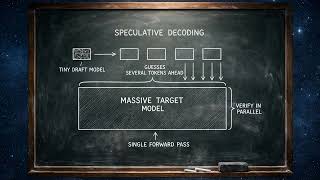
Ready to become a certified watsonx AI Assistant Two GPU kernels can compute the exact same attention, on the same chip, with identical inputs and identical outputs, and one still ... Open-source LLMs are great for conversational applications, but they can be difficult to scale in production and deliver latency ... A user asks a coding assistant to fix a failing test. The prompt lands in a rack of 72 Blackwell GPUs, and from there every ... Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io In this video, we break down the two fundamental stages of We are doing a book club series for AI Download the source code from here: onepagecode.substack.com/ When generating text with Large Language Models, processors often sit idle, starved by memory bandwidth bottlenecks rather ...
The Engineering Behind Llm Inference Speculative Decoding And Long Context.pdf
What is the most accurate information about The Engineering Behind Llm Inference Speculative Decoding And Long Context?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about The Engineering Behind Llm Inference Speculative Decoding And Long Context.
Why is The Engineering Behind Llm Inference Speculative Decoding And Long Context trending right now?
Interest in The Engineering Behind Llm Inference Speculative Decoding And Long Context has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for The Engineering Behind Llm Inference Speculative Decoding And Long Context?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about The Engineering Behind Llm Inference Speculative Decoding And Long Context updated?
We regularly update our database with the latest information, media, and analysis related to The Engineering Behind Llm Inference Speculative Decoding And Long Context.