Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9 Information Guide

  1. Introduction of Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9
  2. Main Features
  3. History
  4. Expert Insights
  5. Conclusion

Introduction of Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9

Full LLM Inference Optimization Explained: KV Cache, Speculative Decoding & Cost | Chapter 9 Guide
Looking for the latest information on Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9? We've compiled comprehensive data, records, and insights about Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9.

Main Features

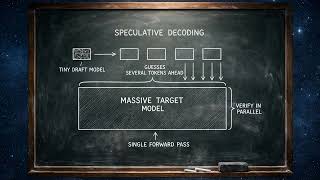
Faster LLMs: Accelerate Inference with Speculative Decoding Update
Explore the main sources for Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9.

History

Full Deep Dive: Optimizing LLM inference Update
Stay updated on Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9's newest achievements.

How KV Cache Speeds Up LLMs for Faster AI Models on GPUs
KV Cache Explained: Optimize LLM Inference
LLM Inference Optimization Explained — From 8 Tokens/sec to 50+
LLM Inference Optimization Explained: KV Cache, Flash Attention, vLLM & SGLang
LLM Inference Optimization: Serving Models Faster & Cheaper
KV Cache in LLM Inference - Complete Technical Deep Dive
LLM Inference Optimization. Coherence in KV Cache Management.  LLM Intra-Turn Cache Dynamics.
LLM Inference Optimization. Coherence in KV Cache Management. LLM Intra-Turn Cache Dynamics.
KV Cache Explained | LLM Inference System Design and GPU Memory
How LLM Inference Actually Scales: KV Cache, Batching & vLLM
LLM Inference Optimization - AI Engineering
The Engineering Behind LLM Inference: Speculative Decoding and Long Context

Expert Insights

Data is compiled from public records and verified media reports.

Last Updated: October 26, 2026

Conclusion

Full KV Cache: The Trick That Makes LLMs Faster News
For 2026, Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9 remains one of the most searched-for information profiles. Check back for the newest reports.

Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.

Summary

Download the source code from here: onepagecode.substack.com/ Ready to become a certified watsonx AI Assistant Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ... Open-source LLMs are great for conversational applications, but they can be difficult to scale in production and deliver latency ... Why does a 70B language model crawl at 8 tokens per second on one setup, then feel instant on another? The difference is ... Want to understand how modern AI systems serve Large Language Models at scale? This video dives deep into We are doing a book club series for AI Engineering by Chip Huyen. During this session, we will discuss and augment Episode eight of The Engineering Behind

Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9.pdf

Size: 1.05 MB · Format: PDF · Secure Download

Download PDF Read Online

Frequently Asked Questions

What is the most accurate information about Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9?

Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9.

Why is Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9 trending right now?

Interest in Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9 has surged recently as more people seek reliable resources, related media, and detailed analysis.

Where can I find related media and updates for Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9?

You can explore extensive galleries, video summaries, and related content directly on this page.

How often is the content about Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9 updated?

We regularly update our database with the latest information, media, and analysis related to Llm Inference Optimization Explained Kv Cache Speculative Decoding Cost Chapter 9.

Related Documents

Popular Topics

Black Triangles After Gum Disease How Orthodontics And Ipr Can Fix Them How To Layer Like A Pro Relativity Explained In 8 Minutes Dameon Pierce Most Freakish Rookie Rb In The Nfl How To Delete Story On Facebook Full Guide Api Gateways Explained Why Your Services Are A Mess Zuplo Review Chatgpt Creates New Countries Gameplay Of Post Apocalyptic Mayhem Multi Player Canada Takes Gold On Home Ice Short Track Highlights Montreal 2026 Worldshorttrack Soapbox1965 November 29 2009 Sometimes 1996 Robert Miles Fable Message Version Privacy Clauses In Servis Ai Acceptable Use Policy Analyzed By The Data Privacy Lawyer How To Stop Getting Privacy Policy Emails Why Candace Owens And Hunter Biden Are A Match Made In Hell Sandro Schwarz Post Match Press Conference New York Red Bulls Vs Philadelphia Union
close