Background on Llm Inference Optimization Async Continuous Batching With Cuda Streams
Looking for the latest information on Llm Inference Optimization Async Continuous Batching With Cuda Streams? We've researched comprehensive data, records, and insights about Llm Inference Optimization Async Continuous Batching With Cuda Streams.
Important Facts
Explore the main sources for Llm Inference Optimization Async Continuous Batching With Cuda Streams.
Developments
Stay updated on Llm Inference Optimization Async Continuous Batching With Cuda Streams's newest achievements.
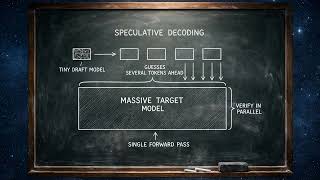
How LLM inference really works: prefill, decode & the KV cache (vLLM explained)
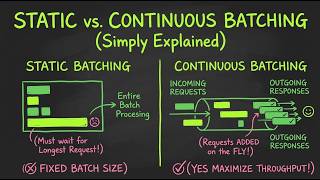
Building an LLM Inference Engine in C++ from scratch: Static & Continuous Batching Explained Easily!
From GPU Bottlenecks to Smooth Chat: Cost-Efficient Architectures for LLM Inference :: Eshcar Hillel
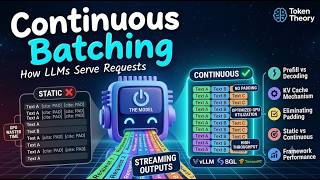
Continuous Batching in LLMs Explained: Fast LLM Inference & Serving (vLLM, TensorRT-LLM)
Expert Insights
Data is compiled from public records and verified media reports.
Last Updated: October 26, 2026
Final Thoughts
For 2026, Llm Inference Optimization Async Continuous Batching With Cuda Streams remains one of the most searched-for information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
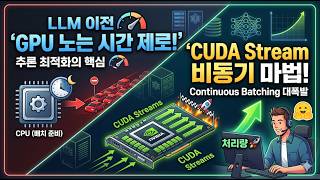
Hugging Face explains how to make Generating one token from a large language model means streaming every weight of the model out of memory, around 140 GB for ... Code: github.com/priyammaz/tinyserve How can a single GPU serve 50 users at virtually the same speed as one? In this video, we break down why naive static 🔹 Explains how Hugging Face asynchronously performs Continuous Batching in LLM inference. 🔹 Traditional synchronous batching ... Deploying Large Language Models into production requires solving real-world latency, memory, and cost bottlenecks. We are doing a book club series for AI Engineering by Chip Huyen. During this session, we will discuss and augment chapter 9 ... Open-source LLMs are great for conversational applications, but they can be difficult to scale in production and deliver latency ... What actually happens on the GPU when you press enter in ChatGPT, Claude or Gemini? We open up vLLM, the open-source ... Welcome back to our video series on building a smaller VLLM for LLama 3.2 1B model. Today we go over Presented at Core C++ 2025 conference, Tel Aviv. What does it take to serve a chatbot with billions of parameters in real time ...
Llm Inference Optimization Async Continuous Batching With Cuda Streams.pdf
What is the most accurate information about Llm Inference Optimization Async Continuous Batching With Cuda Streams?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Llm Inference Optimization Async Continuous Batching With Cuda Streams.
Why is Llm Inference Optimization Async Continuous Batching With Cuda Streams trending right now?
Interest in Llm Inference Optimization Async Continuous Batching With Cuda Streams has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Llm Inference Optimization Async Continuous Batching With Cuda Streams?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Llm Inference Optimization Async Continuous Batching With Cuda Streams updated?
We regularly update our database with the latest information, media, and analysis related to Llm Inference Optimization Async Continuous Batching With Cuda Streams.