Introduction to From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel
Looking for the latest information on From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel? We've researched comprehensive data, records, and insights about From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel.
Core Information
Explore the primary sources for From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel.
Recent Updates
Stay updated on From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel's newest achievements.
The AI Memory Wall: Why LLMs & AI Accelerators Hit a Bottleneck
AI Infrastructure Explained (GPUs, vLLM, and LLM-D)
LLM inference Optimization: From Token to Scale
How to Scale LLM Inference to 10,000+ Users (Without Going Broke)
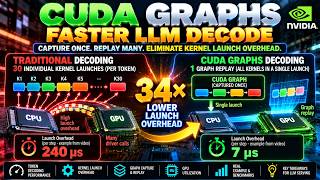
The GPU Isn't Slow, It's Waiting: How CUDA Graphs Fix LLM Decode Latency
The CPU Era Of AI Has Begun
Stop Moving the Weights: A GPU Designed for LLM Inference
DeepSeek Just Showed Everyone How to Make 80% Margins on AI (DeepInfer)
Understanding the LLM Inference Workload - Mark Moyou, NVIDIA
The Engineering Behind LLM Inference: The Memory Wall
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: October 27, 2026
Conclusion
For 2026, From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Presented at Core C++ 2025 conference, Tel Aviv. What does it take to serve a chatbot with billions of parameters in real time ... Try out Telnyx and use code BYCLOUD25 for $25 build credits! Learn more about the Memory Wall here → ibm.biz/~NjOWdJHJy More Try it yourself in the free lab: kode.wiki/4hAjYQq AI infrastructure explained, from a single Serving LLMs at scale is incredibly expensive—but it doesn't have to break your company. If you are struggling with massive Get my FREE agentic engineering config: zenvanriel.com/ai-coding?ref=pLdFQ4r-o4g ⚡ Become a high-earning AI ... Learn how modern AI systems optimize Large Language Model ( Sources & further reading - DeepSeek — DeepInfer code, supported models, and release scope: ...
From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel.pdf
What is the most accurate information about From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel.
Why is From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel trending right now?
Interest in From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel updated?
We regularly update our database with the latest information, media, and analysis related to From Gpu Bottlenecks To Smooth Chat Cost Efficient Architectures For Llm Inference Eshcar Hillel.