Background of Speculative Decoding Faster Llms Same Output
Looking for the latest information on Speculative Decoding Faster Llms Same Output? We've compiled comprehensive data, records, and insights about Speculative Decoding Faster Llms Same Output.
Core Information
Explore the key sources for Speculative Decoding Faster Llms Same Output.
History
Stay updated on Speculative Decoding Faster Llms Same Output's newest achievements.
Speculative Decoding: When Two LLMs are Faster than One
Speculative Decoding: 3× Faster LLM Inference with Zero Quality Loss
Speculative Decoding Explained: Same Answer, Faster (Local LLMs)
What is Speculative Decoding making LLMs faster
This Simple Trick Made ALL LLMs 2x Faster
Speculative Decoding: Free Speed for Your Local LLM — Explained
TensorFold: Faster Local LLM Decoding With Identical Output (Exact Speculative Decoding)
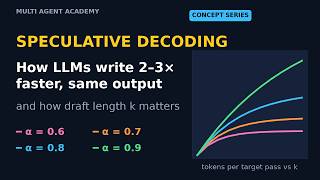
Speculative Decoding Explained: How LLMs Generate 2-3x Faster With the Same Output
Why Speculative Decoding Makes LLMs Faster
Local AI 202: Get Massive Speed-ups with Speculative Decoding
Speculative Decoding — Make LLM Inference Faster Without Changing Output | datarekha
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: October 26, 2026
Conclusion
For 2026, Speculative Decoding Faster Llms Same Output remains one of the most talked-about information profiles. Check back for the latest updates.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Ready to become a certified watsonx AI Assistant Engineer? Register now and use code IBMTechYT20 for 20% off of your exam ... A tiny draft model writes ahead, the big model checks the whole batch in Try Voice Writer - speak your thoughts and let AI handle the grammar: voicewriter.io Make the AI on your own computer Try out and get your free credits now on GenSpark AI, as well as unlimited use of AI Chat and AI Image in 2026 for paid users ... TensorFold is a new free, open-source (Apache-2.0) inference engine that runs language models on your own machine and ... Why can a big language model write two to three times Big models are slow because generation is autoregressive and memory-starved: every token requires a full sequential forward ...
What is the most accurate information about Speculative Decoding Faster Llms Same Output?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Speculative Decoding Faster Llms Same Output.
Why is Speculative Decoding Faster Llms Same Output trending right now?
Interest in Speculative Decoding Faster Llms Same Output has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Speculative Decoding Faster Llms Same Output?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Speculative Decoding Faster Llms Same Output updated?
We regularly update our database with the latest information, media, and analysis related to Speculative Decoding Faster Llms Same Output.