About of Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025
Looking for the latest information on Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025? We've compiled comprehensive data, records, and insights about Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025.
Important Facts
Explore the primary sources for Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025.
Latest News
Stay updated on Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025's latest milestones.
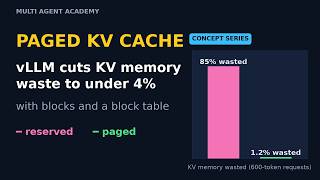
PagedAttention Explained: How vLLM Cuts KV Cache Waste to Under 4%
How PagedAttention Works | The Idea Behind vLLM
Agentic Incident Response - DevConf.CZ 2025
How LLM inference really works: prefill, decode & the KV cache (vLLM explained)
LLM Inference Optimization: Beating the Memory Wall
Full Guide
Data is compiled from public records and verified media reports.
Last Updated: October 27, 2026
Future Outlook
For 2026, Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025 remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Speaker(s): Rahul Belokar, Sagar Jalindar Aivale Large language models (LLMs) are pushing the boundaries of artificial ... What if the next major improvement in When generating text with Large Language Models, processors often sit idle, starved by Speaker(s): Marina Volkova AI won't take your job (yet) because building Authors: Woosuk Kwon (UC Berkeley), Zhuohan Li (UC Berkeley), Siyuan Zhuang (UC Berkeley), Ying Sheng (Stanford ... Same GPU. More users. How does that work? Speaker(s): Birol Yildiz Incidents are becoming increasingly complex, yet responders are still overwhelmed by noise. Today ... What actually happens on the GPU when you press enter in ChatGPT, Claude or Gemini? We open up vLLM, the open-source ...
What is the most accurate information about Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025.
Why is Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025 trending right now?
Interest in Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025 has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025 updated?
We regularly update our database with the latest information, media, and analysis related to Pagedattention Revolutionizing Llm Inference With Efficient Memory Management Devconf Cz 2025.