Background of How To Scale Llm Applications With Continuous Batching
Looking for the latest information on How To Scale Llm Applications With Continuous Batching? We've researched comprehensive data, records, and insights about How To Scale Llm Applications With Continuous Batching.
Main Features
Explore the key sources for How To Scale Llm Applications With Continuous Batching.
Developments
Stay updated on How To Scale Llm Applications With Continuous Batching's newest achievements.
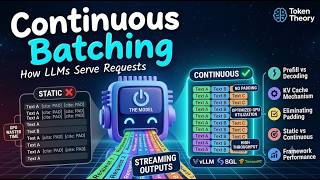
Continuous Batching in LLMs Explained: Fast LLM Inference & Serving (vLLM, TensorRT-LLM)
L-52: Continuous batching – vs Static Batching for LLM Inference #llm #inference
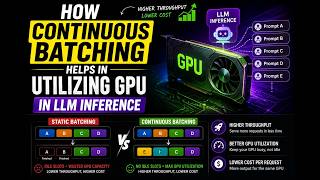
How Continuous Batching Helps In Utilizing GPU In LLM Inference | LLM | Batching
Paged Attention and Continuous Batching: How vLLM Actually Works
How to Scale LLM Inference to 10,000+ Users (Without Going Broke)
Continuous Batching Explained: How AI Handles Thousands of Requests
Continuous Batching: AI's Engine
LLM Optimization Lecture 5: Continuous Batching and Piggyback Decoding
Why LLM GPUs Waste 76% of Their Capacity Continuous Batching
Deep Dive
Data is compiled from public records and verified media reports.
Last Updated: October 26, 2026
Conclusion
For 2026, How To Scale Llm Applications With Continuous Batching remains one of the most searched-for information profiles. Check back for the newest reports.
Disclaimer: Disclaimer: All information is compiled from publicly available data, media reports, and analysis. Actual details may vary.
Summary
Generating one token from a large language model means streaming every weight of the model out of memory, around 140 GB for ... Welcome to Uplatz, where we explore the technologies, business models, economic shifts, and engineering concepts shaping the ... Ever wondered how AI companies serve thousands of We build up how vLLM serves thousands of users from two pieces of bookkeeping: the scheduler and the KV cache memory ... The provided technical article outlines the fundamental mechanisms and optimization techniques necessary to understand and ... How can a single GPU serve 50 users at virtually the same speed as one? In this video, we break down why naive static Open-source LLMs are great for conversational Why do expensive GPUs waste so much capacity while serving large language models? The problem is static
How To Scale Llm Applications With Continuous Batching.pdf
What is the most accurate information about How To Scale Llm Applications With Continuous Batching?
Our platform aggregates the most comprehensive and up-to-date insights, ensuring you get relevant details about How To Scale Llm Applications With Continuous Batching.
Why is How To Scale Llm Applications With Continuous Batching trending right now?
Interest in How To Scale Llm Applications With Continuous Batching has surged recently as more people seek reliable resources, related media, and detailed analysis.
Where can I find related media and updates for How To Scale Llm Applications With Continuous Batching?
You can explore extensive galleries, video summaries, and related content directly on this page.
How often is the content about How To Scale Llm Applications With Continuous Batching updated?
We regularly update our database with the latest information, media, and analysis related to How To Scale Llm Applications With Continuous Batching.